An LLM penetration test finds out whether an attacker can use your model, tools, RAG pipeline or cloud IAM to steal data or gain privileges. AI red teaming measures whether the model says things it should not. In the LLM penetration testing vs AI red teaming decision, the pentest is the one that maps to business risk. If your LLM touches internal data, tools or user accounts, buy it first.
The short answer
- LLM penetration testing targets the deployed system (app, RAG, tools, MCP servers, IAM) and reports exploitable findings with severity and remediation.
- AI red teaming targets model behavior (harmful output, bias, jailbreak resistance) and reports attack success rates per harm category, not vulnerabilities.
- Prompt injection is a security vulnerability class and belongs in the pentest. Jailbreaks are a behavior artifact and belong in the red team.
- Buy the pentest first if the model can reach data, tools or accounts.
Key takeaways
- An LLM pentest reports exploitable impact on data, tools and privileges. AI red teaming reports harm-category attack success rates.
- Prompt injection is a security vulnerability with no patch; jailbreaks are a behavior issue tied to model policy.
- Most real agent incidents (Slack AI, EchoLeak, GitHub and Supabase MCP) were application and IAM failures, not model-behavior failures.
- EU AI Act Article 55 mandates adversarial testing only for GPAI providers with systemic risk; Article 15 drives security testing for high-risk systems.
- Report non-deterministic findings as attack success rates over a stated number of trials, never as a single transcript.
What is the difference between LLM penetration testing and AI red teaming?
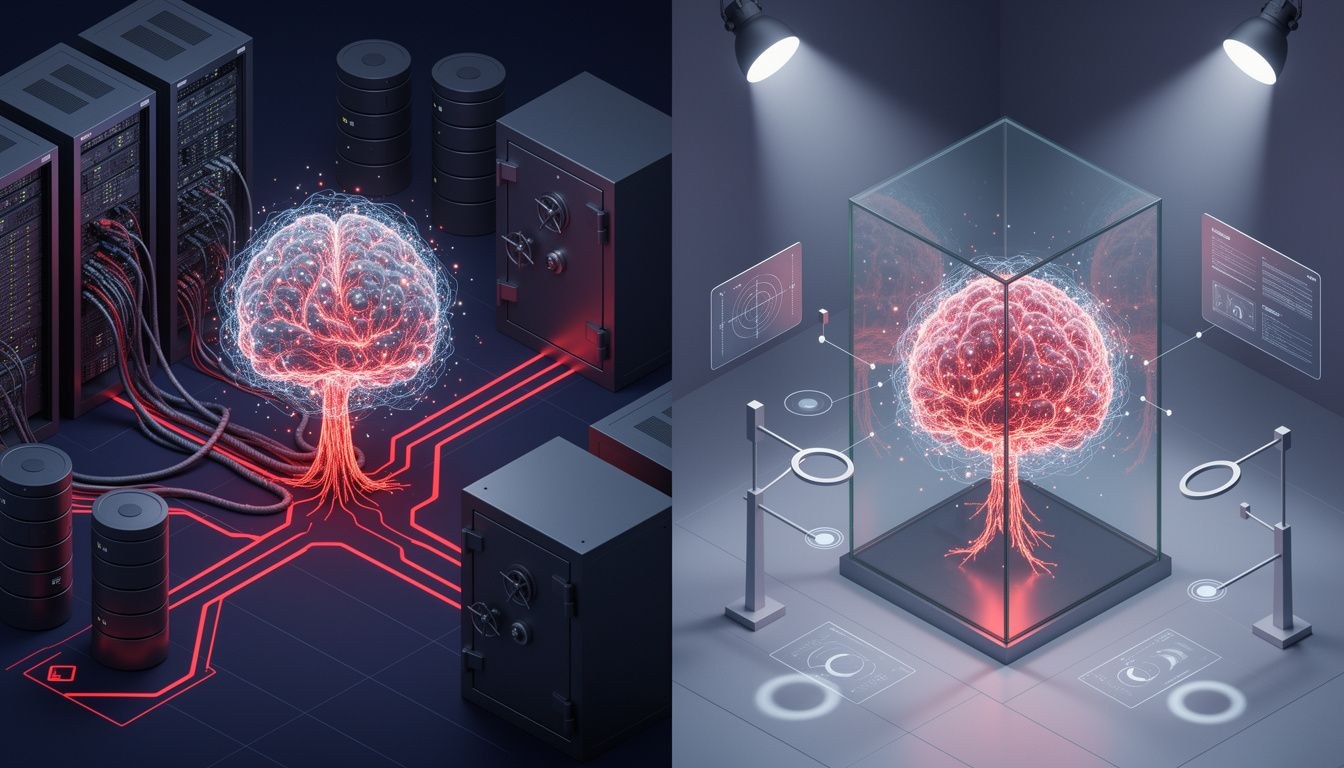
An LLM penetration test asks whether an attacker can use your model, its tools, its retrieval layer or its cloud identity to read data, take actions or gain privileges they should not have. AI red teaming asks whether the model stays inside an acceptable-behavior policy.
The pentest produces findings an engineer can fix. The red team produces measurements a trust-and-safety or governance team can sign off on.
Part of the confusion is vocabulary. Microsoft’s AI Red Team includes traditional security exploitation in its remit, while safety teams at model labs use the same phrase for behavior elicitation only. Two quotes for “AI red teaming” can describe engagements that share almost no test cases. Judge the statement of work and the sample deliverable, not the label.
| Dimension | LLM penetration test | AI red teaming (behavior) |
|---|---|---|
| Target | Deployed system: app, system prompt handling, RAG and vector store, tools, MCP servers, agent orchestration, cloud IAM | The model and its guardrails |
| Attacker model | Malicious user, poisoned document author, compromised data source, rogue tool | User trying to elicit disallowed output |
| Output | Reproducible findings with evidence, severity, remediation | Attack success rate (ASR) per harm category, guardrail coverage, model card inputs |
| Buyer | CISO, AppSec, platform team | Trust and safety, responsible AI, compliance |
| Typical trigger | SOC 2, ISO 27001, insurers, customer security reviews, EU AI Act Art. 15 | EU AI Act Art. 55, public model products |
| Cost driver | Number of tools, data sources, agents and tenants in scope | Harm categories, trial counts, human annotation hours |
| Retest cadence | After each fix and each release | Whenever the model or guardrail version changes |
When is a finding a security issue, and when is it model behavior?
A finding is a security issue when it has exploitable impact on systems, data or privileges you own. If the only impact is that the model produced text it should not have, it is a behavior finding. That one question determines which report the finding lands in and which budget covers it.
Consider the two incidents most often cited as “AI gone wrong.” Chevrolet of Watsonville’s chatbot agreed to sell a Tahoe for $1 in December 2023. In February 2024, the BC Civil Resolution Tribunal held Air Canada liable in Moffatt v. Air Canada for refund terms its chatbot invented.
Neither was a behavior failure in the red team sense. Both came from an LLM front end with no authorization boundary on what it could commit to and no grounding control on what it could assert. Those are application design flaws, and a pentest that covers business logic finds them.
A related rule: refusals are not security. A refusal is a behavior outcome. A bypassed refusal that also triggers a tool call, leaks a document or sends data outbound is a vulnerability.
Jailbreak vs prompt injection
A jailbreak attacks the model’s own policy layer to get past its refusals. A prompt injection attacks the application’s trust boundary by smuggling instructions through content the system treats as data. Jailbreaks belong in a red team report. Prompt injection is a vulnerability class and belongs in the pentest.
Greshake et al. established indirect prompt injection in their 2023 paper “Not what you’ve signed up for”: instructions planted in retrieved documents, web pages, emails, issue bodies or code comments run with the application’s privileges. The incident record since then follows that pattern. PromptArmor showed Slack AI leaking private channel content through injected messages in August 2024.
In June 2025, Aim Security disclosed EchoLeak (CVE-2025-32711) in Microsoft 365 Copilot. A crafted email, later pulled into Copilot’s context, could exfiltrate data without the user clicking anything.
| Issue | Attack surface | Who gets hurt | Patchable? |
|---|---|---|---|
| Jailbreak | Model policy and refusals | Mostly the provider’s reputation and users | Mitigated per model version, never closed |
| Prompt injection | Any untrusted input the model reads | Your data, your tools, your tenants | No. Contained by architecture |
| Data and model poisoning | Training data, fine-tunes, RAG corpus | Everyone downstream of the corpus | Partly, via provenance and ingestion controls |
| Excessive agency | Tool scopes and permissions | Whatever the tools can reach | Yes, through least privilege and confirmation gates |
If a vendor files prompt injection under “jailbreak resistance,” they probably tested only the chat box and missed every indirect path that actually leads to a breach.
What does a real LLM pentest test?
It tests the kill chain from untrusted input to business impact, not the model in isolation. Scoping starts with Simon Willison’s “lethal trifecta” (2025): an agent is exfiltration-prone when it has access to private data, exposure to untrusted content and an outbound channel. Wherever all three meet is where testing hours go first.
Coverage should map to the OWASP Top 10 for LLM Applications 2025. Excessive agency (LLM06), improper output handling (LLM05), sensitive information disclosure (LLM02) and vector and embedding weaknesses (LLM08) usually produce the highest-severity findings. Techniques map to MITRE ATLAS. In practice:
- Indirect injection sweep across the RAG corpus, email, tickets, web browsing, code comments and rules files such as
.cursor/rulesandcopilot-instructions.md. - Tool-call authorization: can the agent call
delete_accountorsend_emailwithout a fresh consent check tied to the requesting user? - RAG access control: cross-tenant retrieval, IDOR on document endpoints, metadata filters enforced client-side.
- Output handling: model output rendered as HTML, Markdown image beacons, SQL or shell commands.
- Cloud IAM blast radius: what the agent’s service identity can reach if fully hijacked, including SSRF via tool invocation to metadata endpoints.
- Memory and multi-agent trust: poisoned long-term memory that detonates later, and sub-agents with more privilege than the task needs.
MCP gets its own line in the scope
Invariant Labs documented tool-description poisoning in April 2025. Known variants include “rug pull” redefinition after approval, cross-server tool shadowing and confused-deputy token passthrough.
Invariant Labs then showed the GitHub MCP server leaking private repos through a public-issue injection in May 2025. In June 2025, Asana took its own MCP server offline after a flaw that could expose data across customer organizations. General Analysis showed the Supabase MCP bypassing row-level security through its service role in July 2025. Anthropic’s MCP Inspector had an RCE, CVE-2025-49596.
Testers should also check whether your servers follow the spec’s OAuth 2.1 and RFC 8707 resource indicator guidance or simply bind to 0.0.0.0 without auth. Most agent exploits end in privilege escalation, not in anything the model “said,” so scoping the LLM alone wastes the engagement. Our LLM application penetration testing covers the full stack by default.
When the model is a third-party API
You test your integration, not the provider’s weights. OpenAI, Anthropic or Azure OpenAI own the model. You own the system prompt, the retrieval corpus, the tools, the credentials and the authorization decisions, and provider-side guardrails know nothing about any of them.
Settle three things before day one. Check the provider’s usage policy, since heavy jailbreak campaigns against a hosted model can breach its terms while integration testing usually does not. Sign a data-handling agreement, because proving exfiltration touches real PII. Get a safe-harbor letter covering the tools and SaaS tenants the agent can reach.
What does AI red teaming measure, and can open-source tools replace either engagement?
AI red teaming measures how often the model fails across a defined harm taxonomy: toxicity, bias, harmful instructions, CBRN uplift, self-harm, sexual content, hallucination, sycophancy and over-refusal. The method is structured elicitation, from single-turn prompts to crescendo-style multi-turn escalation and persona or encoding tricks, with human raters scoring outputs against an annotation protocol.
Good red teams report ASR per category with sample sizes, compare against benchmarks such as HarmBench, JailbreakBench or StrongREJECT, and run a gap analysis on guardrails like Llama Guard, NeMo Guardrails or Azure Prompt Shields. Without a harm taxonomy and an annotation protocol, it is compliance theater. You will receive a slide deck of cherry-picked transcripts.
That work is the scope of our LLM jailbreak and guardrail testing, on a separate SOW from the pentest. There is also a third bucket most buyers never scope: classical adversarial ML as defined in NIST AI 100-2, covering evasion, poisoning, membership inference and model extraction. It matters mainly if you train, fine-tune or host your own model.
Garak, PyRIT and Promptfoo
Run them, but do not mistake them for an engagement. Garak, PyRIT, Promptfoo, Inspect AI and DeepTeam give you payload coverage and regression testing. Benchmarks like AgentDojo and InjecAgent show where an agent design is weak. Wire them into CI and rerun on every model or prompt change.
They do not do threat modeling, authorization analysis, cloud IAM review or business-logic chaining. A scanner can confirm the model follows an injected instruction. It cannot tell you that the instruction reaches a tool holding a service-role key with write access to production. A vendor whose methodology starts and ends with these tools is selling a scanner dressed up as an engagement.
How do you score prompt injection when there is no patch and CVSS does not fit?
Use CVSS v4.0 for discrete technical flaws and a separate impact model, with stated residual risk, for injection-class issues. An auth bypass in an MCP server, SSRF through a tool or an IDOR on a RAG endpoint gets a normal CVSS v4.0 vector. The supplemental Safety metric covers physical or human-safety consequences.
Prompt injection is different. UK NCSC and OWASP both treat it as unsolved, a residual risk rather than a bug with a fix, so forcing a CVSS vector onto it produces a fake number. Score it on impact, exploitability, data sensitivity and blast radius, then report which architectural controls cap the damage.
Those controls include OpenAI’s instruction hierarchy, Microsoft’s spotlighting, capability-based designs like Google DeepMind’s CaMeL, least-privilege tool scopes, egress allowlists, human confirmation for outbound or destructive actions, and policy enforcement outside the model. Guardrail products are an attack surface too, so “we added a filter” needs its own bypass test before anyone closes the finding.
Non-determinism: a 7.5% success rate is a finding
A single successful transcript is a lead, not a finding. Report ASR over a stated number of trials (20 to 50 per payload family is common), with model version and temperature pinned. If a payload succeeds 3 times in 40, the rate is 7.5%, with a 95% Wilson interval of roughly 2.6% to 19.9%.
Against an agent that reads 10,000 inbound emails a day, that rate is a reliable attack, not a fluke.
Does the EU AI Act require AI red teaming, and which article?
Only for a specific group. Article 55 requires providers of general-purpose AI models with systemic risk to perform model evaluation, including adversarial testing, and to report on it. Those obligations have applied since 2 August 2025. Most enterprises deploy someone else’s model and are not GPAI providers at all.
If you build or integrate a high-risk system, read Article 15. It requires resilience against attempts to manipulate the system, which in practice means security testing of the integration. High-risk obligations were scheduled to apply from 2 August 2026, but the European Commission’s Digital Omnibus package proposed pushing them back, so confirm the current timeline before you plan around it.
The US has no equivalent mandate. Executive Order 14110, which directed developers of the most capable dual-use foundation models to report red-team results to the federal government, was revoked on 20 January 2025. Governance frameworks stay voluntary: NIST AI RMF 1.0, the NIST AI 600-1 Generative AI Profile, and ISO/IEC 42001 for a certifiable management system.
Which should you buy first, and what will it cost?
Buy the LLM pentest first if the model can reach internal data, tools or user accounts, which describes most enterprise deployments. It maps to exploitable business risk, produces remediable findings, and is what auditors, insurers and enterprise customers ask about.
| Your situation | Recommended engagement |
|---|---|
| Internal RAG over confidential documents | LLM pentest focused on retrieval access control and output handling |
| Customer-facing support bot | LLM pentest including business-logic and authority limits; light behavior testing |
| Agent with write access to SaaS or cloud | Threat model, then a deep pentest of tool authorization, MCP and IAM |
| Public model product | Both: pentest of the platform, behavior red team of the model |
| Regulated or EU high-risk system | Pentest for Art. 15 robustness, plus red teaming if you are a GPAI provider |
The sequence that holds up: threat model the system, pentest the deployed integration, remediate and retest, add behavior red teaming if you are public-facing or regulated, then run continuous evaluation so fixed issues stay fixed.
Cost, and how to avoid paying twice
Published rate cards are scarce, so compare quotes on scope, not headline price. Pentest cost scales with the number of tools, data sources, agents and tenants in scope. Behavior red teaming scales with harm categories, trial counts and human annotation hours, and a broad taxonomy can cost more than the pentest.
Avoid paying twice by producing one threat model and one system inventory up front and handing both to every vendor. Most of the scoping work is shared; nobody should bill you for it twice.
What each deliverable should contain
A pentest report contains scope, the threat model, findings with reproduction steps, evidence, severity, ASR where relevant, remediation guidance and a retest window. A red team report contains the harm taxonomy, per-category ASR, elicitation methodology, guardrail gap analysis and model card inputs.
The red team report has no “fix this line of code” items, because its remediation is guardrail and policy work. If a sample report blurs the two, the engagement will too. Five RFP questions separate real providers from the rest:
- Show a redacted finding with reproduction steps and trial counts.
- How do you test indirect injection beyond the chat interface?
- Do you review the agent’s cloud IAM and OAuth grants?
- How do you score injection-class issues without a fake CVSS vector?
- Which parts are manual, and which are tool output?
FAQ
Is prompt injection a pentest finding or a red team finding?
It is a pentest finding. Prompt injection crosses the application's trust boundary and can lead to data exfiltration or unauthorized tool calls, which is security impact rather than a policy violation.
Can one engagement cover both LLM penetration testing and AI red teaming?
One vendor can deliver both, but write them as two scopes with two deliverables. They use different methods, different success criteria and different report owners. Share the threat model and system inventory between them so you only pay for scoping once.
Does a provider's model safety work protect my application?
No. OpenAI, Anthropic or Azure OpenAI guardrails cover the model. They know nothing about your system prompt, retrieval corpus, tools, credentials or authorization decisions, which is where most agent breaches happen.
Is MCP server security part of an LLM pentest?
Yes. MCP servers sit on the path from untrusted input to tool execution. Tool-description poisoning, rug pulls, cross-server shadowing, token passthrough and missing authentication all belong in the pentest scope.
If an attack works one time in ten, is it a finding?
Yes. Report it as an attack success rate over a stated number of trials with the model version and temperature pinned. At production volume, a 10% success rate means the attack lands many times a day.
If your agents can read internal data or call tools, start with a threat model and a pentest of the integration. Our MCP server and tool-chain security testing is where most of the real findings live.